GitHubmicrosoft/markitdown★190.9kStars⑂14.2kForks!737Issues + PRs§MITlicense (Apache-2.0, MIT) The rules for using the code. Apache-2.0 and MIT both allow free use, including commercial use. Glossary · Learn moreLicense↻Last push⌘PythonLanguage
Card and link say rockytested.com · posted as @RockyTested
With vs without
With it loadedNot tested yet
No with-skill pass count is on file.
vs
Without itNot tested yet
No baselinebaseline The normal way of doing the same job, used as the yardstick. Rocky compares every claim against a baseline on the same machine. Glossary pass count is on file.
Usefulness is a separate question from “does the repo exist.” It needs the same task run twice. Until that A/B is published, both cells stay blank.
What the test plan says
Build 9 fixture files (DOCX, PPTX, XLSX, PDF, HTML, CSV, JSON, EPUB, and a scanned image-only PDF), each carrying 6 known canary sentences and a known 3x4 table. Convert each and count how many canaries and table cells survive, and whether a real Markdown table comes out.
Four verdicts
One stamp is not the whole story. Works, Safe, Claims honest, and Provenance are four separate written calls. A missing call stays “not tested yet.”
WorksNOT TESTED YETDid it do the thing when Rocky ran it?
No written call is on file. This is not a pass.
SafeNOT TESTED YETSafe to install and run?
No written call is on file. This is not a pass.
Claims honestNOT TESTED YETDoes the pitch match what Rocky measured?
No written call is on file. This is not a pass.
ProvenanceNOT TESTED YETDoes the repo's history check out?
No written call is on file. This is not a pass.
Safety is a hard cap. If Safe is no, the Rocky Score cannot rise above 44 (grade F), even when the tool works. A blank Safe card means not tested yet, not safe. How the four verdicts roll up →
Claim vs what Rocky measured
Claim part
Measured
Result
Finding 1
8 of 9 formats came through with every test sentence and table cell
holds
Finding 2
The one miss was a scanned PDF with no text layer, which returned 1 character
stretched
What it is: A Microsoft tool that converts Office files, PDFs, HTML, CSV, JSON, EPUB and more into Markdown so an agent can read them. Rocky checks what actually survives the conversion, including a scanned page with no text layer. Claim source →
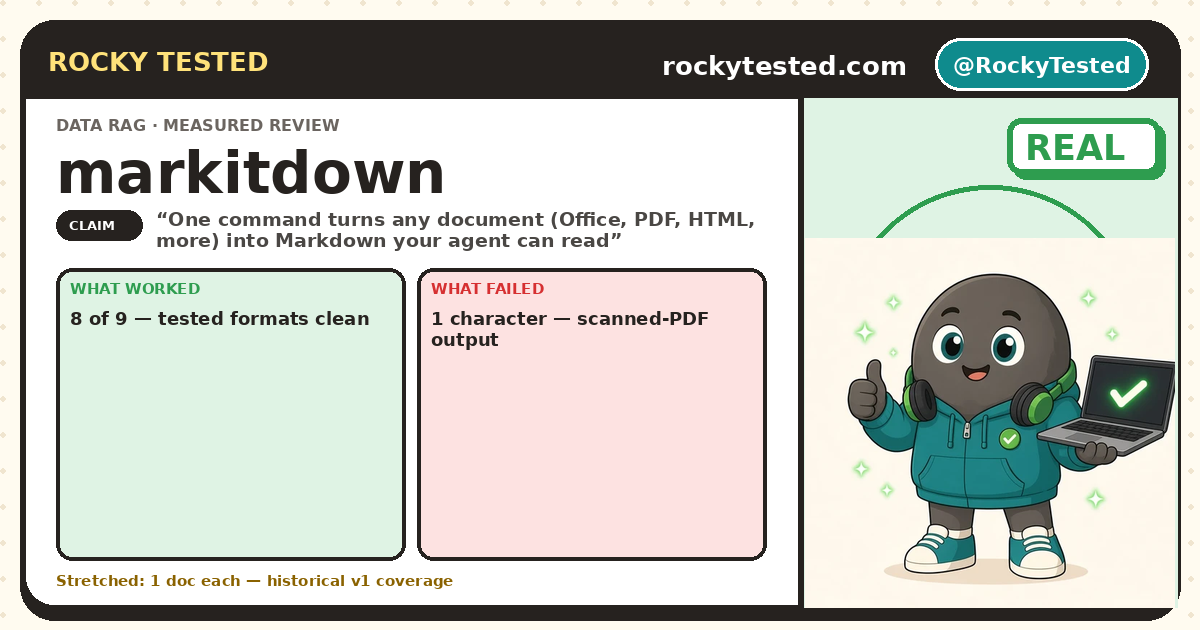
Verdict: REAL
8 of 9 formats came through with every test sentence and table cell. The one miss was a scanned PDF with no text layer, which returned 1 character.
⚠️ Read this before quoting the verdict
"Any document" means documents that contain text. Scans and photos come back empty unless you add an OCR or LLMLLM Large language model: the kind of AI that reads and writes text, like the models behind chat assistants. Glossary · Learn more plugin.
Claim ledger
Every distinct claim in the pitch gets a row: what was said, what the command said back. 1 claim on the ledger: 1 not measured. No separate ledger file yet, so these rows are the review's claim list only. “Not tested” means that claim has no measurement.
? Not tested
“One command turns any document (Office, PDF, HTML, more) into Markdown your agent can read” source
🔍 Coverage: Not stated yet. Rocky only lists the parts a run actually checked.
⚗️ Unproven usefulness. Counting and parsing can settle what the repo claims. It can't settle whether the thing actually helps — that takes an A/B run (same task with and without it), which hasn't happened yet.
Rocky's take: good uses & where it will fail you
Good uses
Office files with text convert cleanlyMaria needs a DOCX contract, PPTX deck, and XLSX budget turned into Markdown for an assistant to read; all 6 test sentences and 16 table cells came through in each file.
Quick batch jobs across many file typesDave has a folder of CSV, HTML, and JSON reports to prep for an agent; each file converted in about 0.5 to 0.7 seconds.
Web pages and ebooks to notesPriya archives an HTML page and an EPUB book as Markdown notes; both kept all 6 of the test sentences intact.
Text-based PDFs you already haveTom converts a PDF report that was exported digitally, not scanned; all 6 sentences and 16 table cells survived.
Where it will fail you
Scanned or photographed pages come back emptySam scans a paper invoice to PDF and converts it; the result is just 1 character, with 0 of 6 sentences and 0 of 16 table cells recovered.
Some formats skip real Markdown tablesLee converts a PDF or JSON file with a table; the 16 cells come through as text but no real Markdown table is produced, unlike with DOCX, PPTX, or XLSX.
EPUB conversion drops table dataRobin converts an EPUB containing a table; unlike CSV, DOCX, PPTX, XLSX, HTML, PDF, and JSON, no table cell data is captured at all.
First run has a slow setup stepOn first use, the install step alone took 146.4 seconds, before any of the 5.4 seconds of actual conversion even started.
🤖 Drafted by an AI model from Rocky's measured results only; every number was machine-checked against the test data. People in the examples are made up.
Where this repo comes from
Not checked yet.
Provenance is age, authors, commitcommit One saved version of a repo's code. Rocky pins the exact commit so anyone can rerun the same code. Glossary · Learn more bursts, and where the README sends you. It is published only from commands Rocky ran. Nothing is guessed, so this section stays blank until that file exists.
Real inputs beside real outputs
1 doc per format in v1; packet expanded for next retest. These are the stored inputs and outputs from the active test set (v1 historical, or v2 document-converters packet when job 46+ has been ingested).
Interactive: hover, focus, or click highlighted input text to light up the extracted span; do the same from the output to trace it back. Click again to unlock.
CleanDOCX
1 doc · 493 output characters · 6 of 6 sentences · 16 of 16 cells
# Rocky fixture

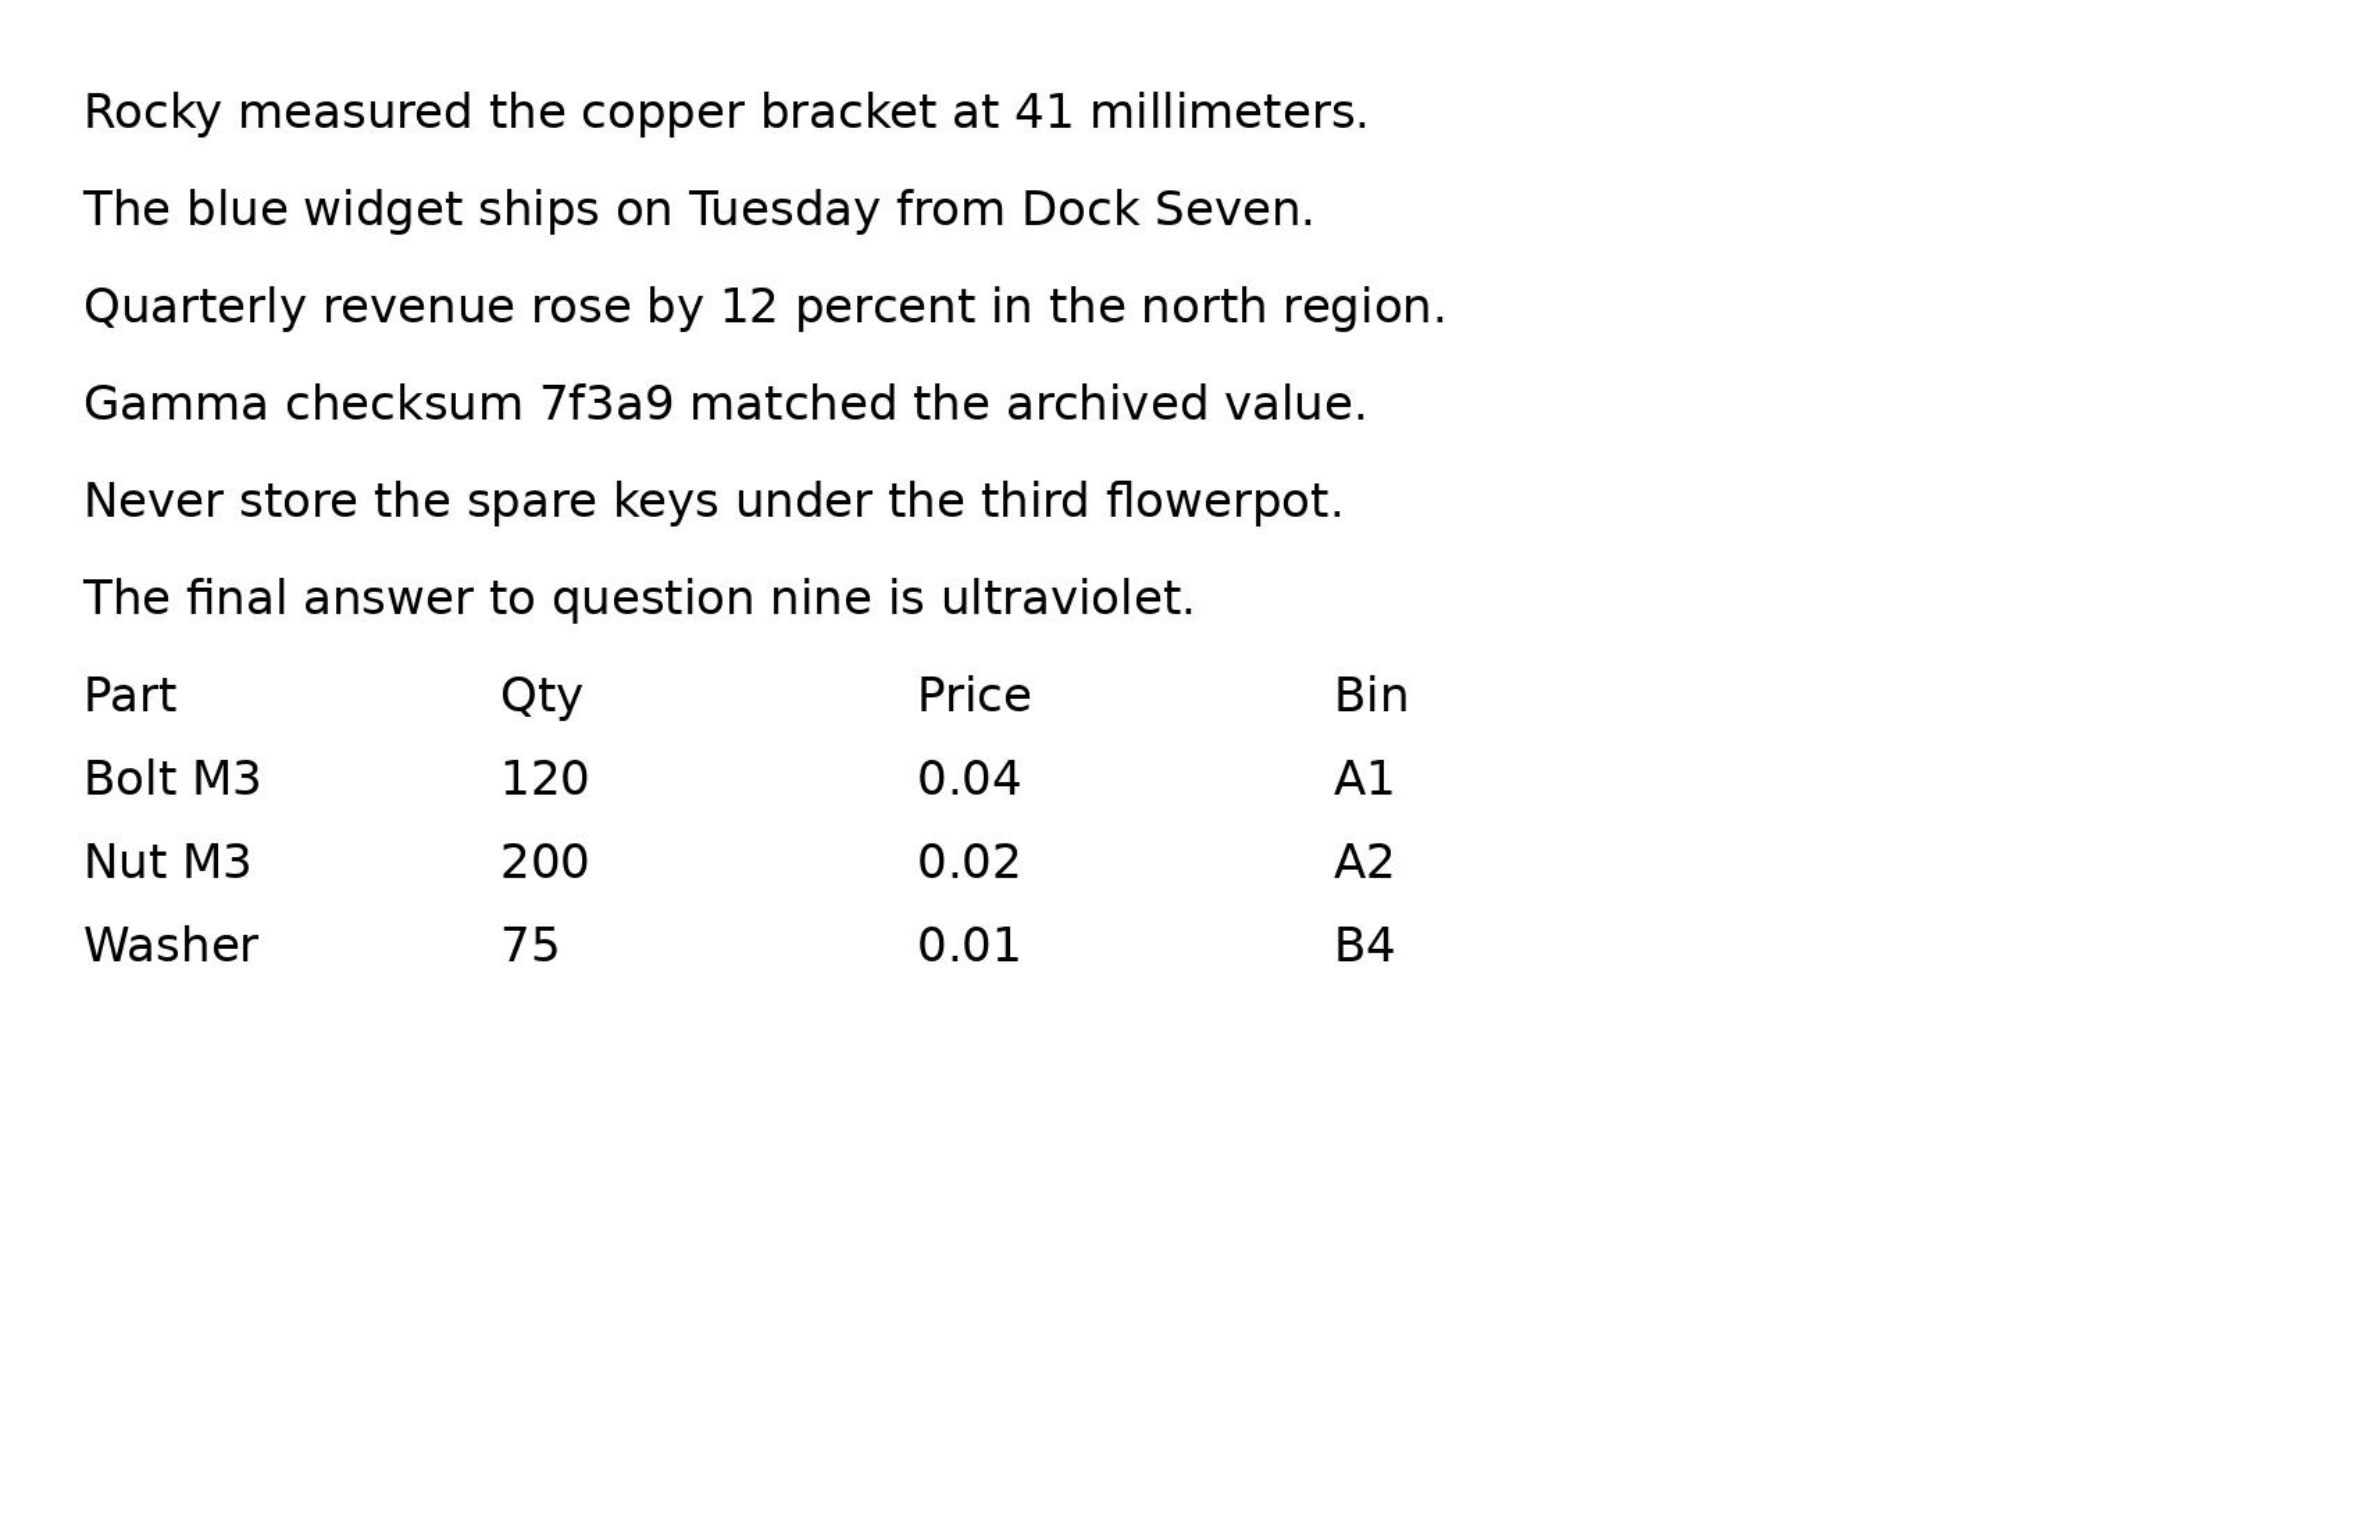
Rocky measured the copper bracket at 41 millimeters.

The blue widget ships on Tuesday from Dock Seven.

Quarterly revenue rose by 12 percent in the north region.

Gamma checksum 7f3a9 matched the archived value.

Never store the spare keys under the third flowerpot.

The final answer to question nine is ultraviolet.

|  |  |  |  |
| --- | --- | --- | --- |
| Part | Qty | Price | Bin |
| Bolt M3 | 120 | 0.04 | A1 |
| Nut M3 | 200 | 0.02 | A2 |
| Washer | 75 | 0.01 | B4 |
<!-- Slide number: 1 -->
# Slide 1
Rocky measured the copper bracket at 41 millimeters.
The blue widget ships on Tuesday from Dock Seven.

<!-- Slide number: 2 -->
# Slide 2
Quarterly revenue rose by 12 percent in the north region.
Gamma checksum 7f3a9 matched the archived value.

<!-- Slide number: 3 -->
# Slide 3
Never store the spare keys under the third flowerpot.
The final answer to question nine is ultraviolet.

<!-- Slide number: 4 -->
| Part | Qty | Price | Bin |
| --- | --- | --- | --- |
| Bolt M3 | 120 | 0.04 | A1 |
| Nut M3 | 200 | 0.02 | A2 |
| Washer | 75 | 0.01 | B4 |
## Parts
| Part | Qty | Price | Bin |
| --- | --- | --- | --- |
| Bolt M3 | 120 | 0.04 | A1 |
| Nut M3 | 200 | 0.02 | A2 |
| Washer | 75 | 0.01 | B4 |

## Notes
| Rocky measured the copper bracket at 41 millimeters. |
| --- |
| The blue widget ships on Tuesday from Dock Seven. |
| Quarterly revenue rose by 12 percent in the north region. |
| Gamma checksum 7f3a9 matched the archived value. |
| Never store the spare keys under the third flowerpot. |
| The final answer to question nine is ultraviolet. |
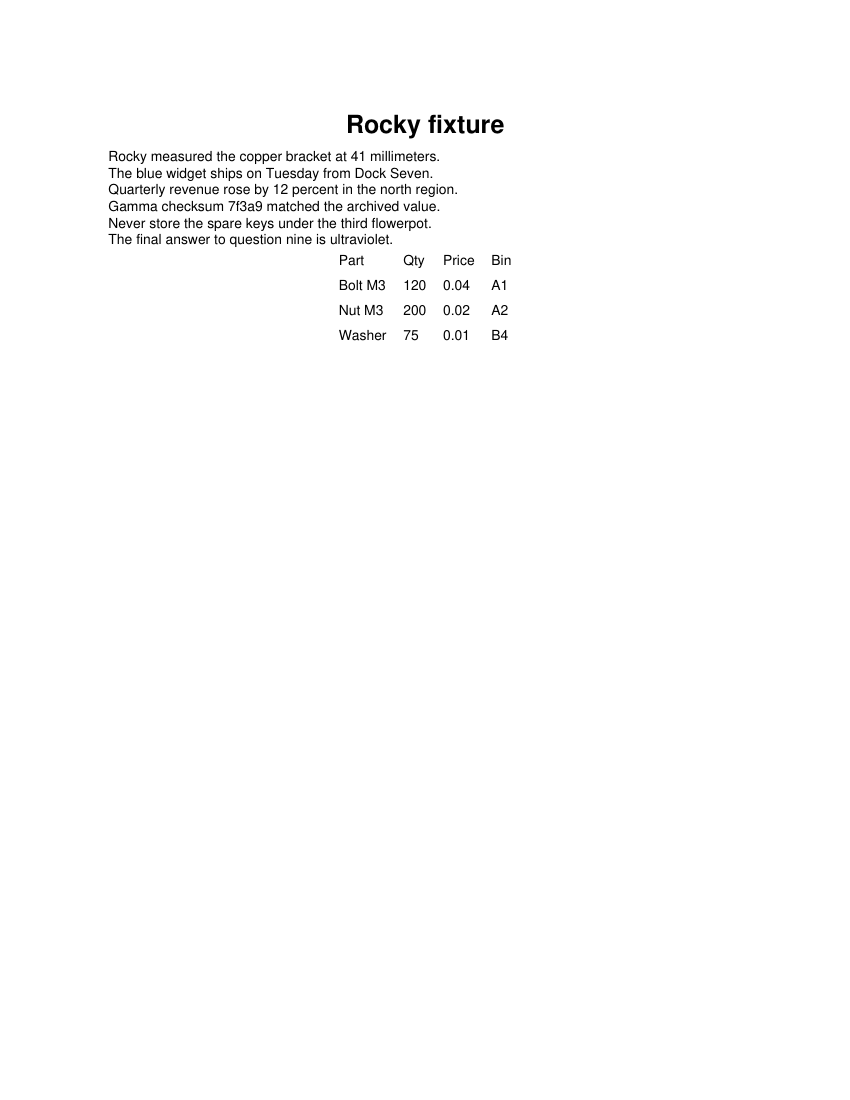
Rocky fixture

Rocky measured the copper bracket at 41 millimeters.
The blue widget ships on Tuesday from Dock Seven.
Quarterly revenue rose by 12 percent in the north region.
Gamma checksum 7f3a9 matched the archived value.
Never store the spare keys under the third flowerpot.
The final answer to question nine is ultraviolet.

Part

Qty Price Bin

Bolt M3

120

0.04

Nut M3

200

0.02

Washer

75

0.01

A1

A2

B4
# Rocky fixture

Rocky measured the copper bracket at 41 millimeters.

The blue widget ships on Tuesday from Dock Seven.

Quarterly revenue rose by 12 percent in the north region.

Gamma checksum 7f3a9 matched the archived value.

Never store the spare keys under the third flowerpot.

The final answer to question nine is ultraviolet.

|  |  |  |  |
| --- | --- | --- | --- |
| Part | Qty | Price | Bin |
| Bolt M3 | 120 | 0.04 | A1 |
| Nut M3 | 200 | 0.02 | A2 |
| Washer | 75 | 0.01 | B4 |
{"notes": ["Rocky measured the copper bracket at 41 millimeters.", "The blue widget ships on Tuesday from Dock Seven.", "Quarterly revenue rose by 12 percent in the north region.", "Gamma checksum 7f3a9 matched the archived value.", "Never store the spare keys under the third flowerpot.", "The final answer to question nine is ultraviolet."], "parts": [{"Part": "Bolt M3", "Qty": "120", "Price": "0.04", "Bin": "A1"}, {"Part": "Nut M3", "Qty": "200", "Price": "0.02", "Bin": "A2"}, {"Part": "Washer", "Qty": "75", "Price": "0.01", "Bin": "B4"}]}
**Title:** Rocky fixture
**Language:** en
**Identifier:** rocky-fx

## Rocky fixture

1. [One](one.xhtml)

# One

Rocky measured the copper bracket at 41 millimeters.

The blue widget ships on Tuesday from Dock Seven.

Quarterly revenue rose by 12 percent in the north region.

Gamma checksum 7f3a9 matched the archived value.

Never store the spare keys under the third flowerpot.

The final answer to question nine is ultraviolet.
Counted from the active metrics file referenced in results/microsoft-markitdown.json (job 13 v1, or a later v2 job after ingest).
Results, charted
Rocky draws these at build time from the run's own numbers. Hover or read the hidden table for exact values. Verdict colors: green holds, yellow stretched, red failed, teal measuring.
Did the document convert? (first run)Green = converted with its text intact. Red = came back empty. The scanned PDF has no text layer, so a text extractor can't read it.
Item
Result
Detail
DOCX
pass
6/6 lines, table
PPTX
pass
6/6 lines, table
XLSX
pass
6/6 lines, table
PDF (text)
pass
6/6 lines
HTML
pass
6/6 lines, table
CSV
pass
16/16 cells
JSON
pass
6/6 lines
EPUB
pass
6/6 lines
PDF (scanned)
fail
0 chars, no text layer
Table cells recovered (of 16)A known 3x4 table (header + 3 rows = 16 cells) embedded in each format, then counted in the Markdown.
Group
Series
Value (cells)
Formats with a table
CSV
16
Formats with a table
DOCX
16
Formats with a table
PPTX
16
Formats with a table
XLSX
16
Formats with a table
HTML
16
Formats with a table
PDF (text)
16
Formats with a table
PDF (scanned)
0
Score
Claim holds weight 35898/9 formats intact; scanned PDF 0/6
Speed / quality vs normal weight 251000.5-0.7 s per file
Graded on 90 of 100 weight points. Parts marked “not measured” are left out of the math, not counted as zero.
Why the 60 appears
The 60 is the reliability subscore, not the overall score: the scorecard caps a single run at 60. The scanned-PDF miss instead lowers claim fidelity to 89 (8 of 9 formats; 0 of 6 expected sentences in the scan). Performance and install both scored 100. With docs and safety not measured, the published rollup is (89×35 + 100×25 + 100×15 + 60×15) ÷ 90 = 89 after rounding.
Medium confidence: claim test with one run per setup. How scores work. Scores only use measured results; parts Rocky didn't measure show as “not measured” and don't count.
Retest history
Testing ends when the run ends. If the repo ships a new version with a bold new claim, or newer models make a fair rematch possible, Rocky reruns the same test packet and the new result lands here next to the old one, so you can compare versions and models side by side.
Rerun it yourself
📦 When the test is done, the exact scripts, raw results and a copy-paste prompt for your own AI agentAI agent An AI that takes actions in steps (runs commands, edits files, browses) instead of only chatting. Glossary · Learn more will appear here.
Repo & thanks
markitdown: Python tool for converting files and office documents to Markdown. Built by @microsoft. Thank you!
📄 Bookmark these 10 GitHub repos that turn any document into text your agent can read
1. MarkItDown (189K stars, MIT)
One command turns Word, PowerPoint, Excel, PDF and HTML files into Markdown. From Microsoft. It needs a plugin and a model to read
https://github.com/microsoft/markitdown
Posts from to , in 8 languages. Checked . Found with X search for links to the repo; more may exist. Oldest first:
Earliest we found@pimoba2019An open-source tool worth knowing: Microsoft's MarkItDown converts PDF, Word, Excel, and other files to Markdown for easier integration into text-analysis workflows. Its official focus is on preserving structures such as headings, lists, and tables, not high-fidelity layout conversion. My take: for a research assistant, organize the input first, then let the model summarize. Source and docs:一个值得了解的开源工具:微软 MarkItDown,把 PDF、Word、Excel 等文件转成 Markdown,方便接入文本分析流程。官方定位偏向保留标题、列表、表格等结构,并非高保真排版转换。我的思考:做资料助手,先把输入整理好,再让模型总结。源码与说明:English translation · Chinese original ❤️ 0 · 🔁 0 · 📊 8open
@Gyome1_24 AI tools that replace $500/month in subscriptions
transcribe, translate, design, run models locally. free in your browser or on your laptop
documents & learning
1.) → clean AI-ready text from any site
2.) → PDF, Word, Excel,❤️ 43 · 🔁 11 · 📊 2.1Kopen
@XsMiguon itmarkitdown is a lightweight open source tool by microsoft that converts various file formats straight into clean markdown for llm and text workflows. handy if you're tired of writing messy parsing scripts. repo in reply :❤️ 0 · 🔁 0 · 📊 1open
@Marco_Exito1.
Converts PDFs, Office files, HTML, and images into Markdown that is ideal for feeding into any AI.
Microsoft released it publicly after using it internally.
You start with messy documents and end with data your LLM can read.1.
Convierte PDFs, Office, HTML e imágenes en markdown perfecto para alimentar cualquier IA.
Microsoft lo abrió al público después de usarlo internamente.
Empiezas con documentos sucios, terminas con datos que tu LLM puede leer.English translation · Spanish original ❤️ 78 · 🔁 2 · 📊 9.6Kopen
All 25 posts, oldest first
Earliest we found@pimoba2019An open-source tool worth knowing: Microsoft's MarkItDown converts PDF, Word, Excel, and other files to Markdown for easier integration into text-analysis workflows. Its official focus is on preserving structures such as headings, lists, and tables, not high-fidelity layout conversion. My take: for a research assistant, organize the input first, then let the model summarize. Source and docs:一个值得了解的开源工具:微软 MarkItDown,把 PDF、Word、Excel 等文件转成 Markdown,方便接入文本分析流程。官方定位偏向保留标题、列表、表格等结构,并非高保真排版转换。我的思考:做资料助手,先把输入整理好,再让模型总结。源码与说明:English translation · Chinese original ❤️ 0 · 🔁 0 · 📊 8open
@Gyome1_24 AI tools that replace $500/month in subscriptions
transcribe, translate, design, run models locally. free in your browser or on your laptop
documents & learning
1.) → clean AI-ready text from any site
2.) → PDF, Word, Excel,❤️ 43 · 🔁 11 · 📊 2.1Kopen
@XsMiguon itmarkitdown is a lightweight open source tool by microsoft that converts various file formats straight into clean markdown for llm and text workflows. handy if you're tired of writing messy parsing scripts. repo in reply :❤️ 0 · 🔁 0 · 📊 1open
@Marco_Exito1.
Converts PDFs, Office files, HTML, and images into Markdown that is ideal for feeding into any AI.
Microsoft released it publicly after using it internally.
You start with messy documents and end with data your LLM can read.1.
Convierte PDFs, Office, HTML e imágenes en markdown perfecto para alimentar cualquier IA.
Microsoft lo abrió al público después de usarlo internamente.
Empiezas con documentos sucios, terminas con datos que tu LLM puede leer.English translation · Spanish original ❤️ 78 · 🔁 2 · 📊 9.6Kopen
@zhishen63629282Before building a knowledge base, convert office files to Markdown. Microsoft's MarkItDown supports PDF, Word, PPT, and Excel, and is MIT-licensed.
Getting started: pip install 'markitdown[all]'; markitdown file.pdf -o file.md.
Basic conversion runs locally; Azure APIs cost extra. It focuses on content extraction, so check complex layouts.做知识库前,先把办公文件转成 Markdown。微软 MarkItDown 支持 PDF、Word、PPT、Excel,MIT 开源。
上手:pip install 'markitdown[all]';markitdown 文件.pdf -o 文件.md。
基础转换走本地;Azure 接口另计费。侧重内容提取,复杂排版要复核。English translation · Chinese original ❤️ 0 · 🔁 0 · 📊 9open
@Techbruneth1.
Convert PDF, Office documents, HTML, and images to Markdown and feed them directly to any AI.
Microsoft used it internally before open-sourcing it.
Start with a pile of messy documents and end with data an LLM can read.1.
把 PDF、Office 文档、HTML 和图片转成 markdown,直接喂给任何 AI。
微软内部先用,后来才对外开源。
从一堆脏文档开始,到最后变成 LLM 能读的数据。English translation · Chinese original ❤️ 6 · 🔁 0 · 📊 978open
@sun_jinwei20915The Word document became text, but the delivery date in the screenshot did not come through. The file looked complete, but one crucial sentence was lost.
Microsoft's MarkItDown OCR plugin can recognize embedded document images and insert their text into the converted output.
One detail: if no model client is configured, it skips OCR. Converting a file does not mean the text inside its images was read.
Suggested tag: #AI工具
[Microsoft project documentation](Word转成了文字,截图里的交付日期却没跟过来。文件看着齐,关键一句丢了。
微软的MarkItDown OCR插件能识别文档嵌图,把图中文字插入转换结果。
有个细节:没配置模型客户端,它会跳过OCR。能转文件,不等于图里的字也读到了。
建议标签:#AI工具
[微软项目说明](English translation · Chinese original ❤️ 1 · 🔁 0 · 📊 117open
@AneesManzo44813MarkItDown HTML→Markdown check:
• “Price (USD / month)” header: units survived.
• “$” and “/ month” added with CSS: units disappeared; “20” survived.
Synthetic local test, v0.1.8. Check units before feeding extracted text to an LLM.❤️ 0 · 🔁 0 · 📊 3open
@yesjinzThe product introduction is in PPT, the specifications are in Excel, and the manual is another PDF. To have AI compare these materials, you first need to handle the different formats.
Microsoft's open-source MarkItDown can convert them to Markdown while trying to preserve headings, lists, and tables, for use in document organization or a knowledge base.
It focuses on extracting content, so complex layouts still need checking.产品介绍在 PPT,参数在 Excel,说明书又是一份 PDF。让 AI 对照这些资料,先得处理各种格式。
微软开源的 MarkItDown 可以把它们转成 Markdown,尽量保留标题、列表和表格,再用于资料整理或知识库。
它侧重提取内容,复杂排版仍要检查。English translation · Chinese original ❤️ 1 · 🔁 0 · 📊 75open
@YoDevpOfficial repository (Python, and it also includes an MCPMCP Model Context Protocol: a standard plug that lets AI assistants use outside tools and data (files, browsers, databases). Glossary · Learn more server for use from your agent):Repo oficial (Python, también trae servidor MCP para usarlo desde tu agente):English translation · Spanish original ❤️ 0 · 🔁 0 · 📊 7open
@canpjllMicrosoft's open-source MarkItDown can convert PDF, Word, Excel, PPT, and other formats to Markdown for ChatGPT or Codex to read and analyze.
Install: pip install 'markitdown[all]'
Usage: markitdown file.pdf > file.md
#GitHub #Codex #AI工具微软的开源工具 MarkItDown,可以把 PDF、Word、Excel、PPT 等转成 Markdown,方便交给 ChatGPT / Codex 阅读分析。
安装:pip install 'markitdown[all]'
用法:markitdown file.pdf > file.md
#GitHub #Codex #AI工具English translation · Chinese original ❤️ 5 · 🔁 0 · 📊 312open
@rina_draws5pmThe MarkItDown episode is up.
It was made by Microsoft,
and it converts files in various formats to Markdown.
I checked it only against the README,
so I am holding off on a verdict.
▶markitdown 편 올라감
마이크로소프트에서 만든 건데
여러 형식 파일을 마크다운으로 바꿔주는 도구임
README 기준으로만 확인해서
판정은 지켜보기로 함
▶English translation · Korean original ❤️ 0 · 🔁 0 · 📊 1open
@lxy71Microsoft's free MarkItDown turns Word docs into Markdown you can review before using it with AI.
Python 3.10–3.14, in a venv:
pip install 'markitdown[docx]'
markitdown brief.docx -o brief.md
Check headings and tables against the original.❤️ 0 · 🔁 0 · 📊 17open
@asrar_rgTool name: MarkItDown 🛠️
It works with PDF, Word, Excel, PowerPoint, and more.
Step-by-step installation instructions are in the Digital Secrets community on Telegram below 👇اسم الأداة: MarkItDown 🛠️
تشتغل مع PDF وWord وExcel وPowerPoint وغيرها
وطريقة التحميل خطوة بخطوة في مجتمع أسرار الرقمية على التليجرام 👇English translation · Arabic original ❤️ 2 · 🔁 0 · 📊 61open
@luchenyang13You cannot avoid this when building RAGRAG Retrieval-augmented generation: look up relevant documents first, then let the model answer using them. Glossary · Learn more: Microsoft's MarkItDown converts PDF, Word, PPT, Excel, and HTML to Markdown before feeding it to a model.
pip install is all it takes. It is an established tool with 189 thousand stars and recently returned to trending.做 RAG 的绕不开这个:微软的 markitdown,PDF/Word/PPT/Excel/HTML 全转 Markdown 再喂模型。
pip install 就能用,18.9 万 star 的老工具,最近又回到 trending 了。English translation · Chinese original ❤️ 2 · 🔁 0 · 📊 127open
@FreeSites_com@RoundtableSpace FREE tool turns PDFs, Word docs, PowerPoints and Excel files into clean text an AI can actually work with.
Markitdown By Microsoft $MSFT❤️ 1 · 🔁 0 · 📊 31open
@TheHour2359Source URLs
Anthropic Scion
GhidraMCP
REA
Microsoft MarkItDown
Docling
ArtCraft WordCraft
Cyberpunk 2077 Titanfall mod출처 URL
Anthropic Scion
GhidraMCP
REA
Microsoft MarkItDown
Docling
ArtCraft WordCraft
사이버펑크 2077 타이탄폴 모드English translation · Korean original ❤️ 1 · 🔁 0 · 📊 105open
@irsiylPDFs can look the same while containing different things.
Compared my own files with the free, open-source MarkItDown.
Text included → extracted Japanese
Image only → blank (no OCR)
Conversion: markitdown a.pdf -o out.markdown
See the official source for setup instructions. Do not ask it to make brilliant deductions from material it could not read.PDF、見た目が同じでも中身は違う。
無料OSS「MarkItDown」で自作資料を比較。
文字入り→日本語を抽出
画像だけ→空欄(OCRなし)
変換:markitdown a.pdf -o out.markdown
導入手順は公式へ。読めてない資料に名推理させないでね。English translation · Japanese original ❤️ 0 · 🔁 0 · 📊 9open
@pizaniadvConverts Word, PDF, spreadsheets, and PowerPoint to Markdown, the text AI reads.
→ pip install 'markitdown[all]'
→ MIT License
→ The caveat, according to the README: it may not be the best option for faithful conversion intended for human reading.Converte Word, PDF, planilha e PowerPoint em Markdown, o texto que a IA lê.
→ pip install 'markitdown[all]'
→ Licença MIT
→ O porém, diz o README: pode não ser a melhor opção para conversão fiel, para leitura humana.English translation · Portuguese original ❤️ 0 · 🔁 0 · 📊 6open
@victor_explore📄 Bookmark these 10 GitHub repos that turn any document into text your agent can read
1. MarkItDown (189K stars, MIT)
One command turns Word, PowerPoint, Excel, PDF and HTML files into Markdown. From Microsoft. It needs a plugin and a model to read❤️ 22 · 🔁 7 · 📊 1.1Kopen
@manivardhan123Before blaming your AI, check what it actually read. Microsoft’s MarkItDown converts PDFs, Word, Excel and slides into Markdown for AI workflows. Convert → inspect the output → then use it.❤️ 0 · 🔁 0 · 📊 3open
@oliviscusAIrepo:
follow for more useful tools like this.❤️ 1 · 🔁 0 · 📊 198open
@yn99445170Do not rush to pay for a file-conversion tool subscription; this Microsoft tool is actually open source.
MarkItDown can convert PDF, Word, and Excel to Markdown that is easy to feed to AI, and it runs locally.
This kind of handy little tool is more practical than a pile of chat wrappers, but do not expect lossless conversion of complex layouts.
Source:别急着给文件转换工具充会员,微软这东西居然是开源的。
MarkItDown,能把 PDF、Word、Excel 转成方便喂给 AI 的 Markdown,本地就能跑。
我靠,这种省事的小工具比一堆聊天套壳实在多了,不过复杂排版别指望无损。
源码:English translation · Chinese original ❤️ 0 · 🔁 0 · 📊 6open
Ran it yourself?
Share your rerun
Download the rerun bundle above.
Run it, or paste the prompt into your AI agent.
Post your results.json (a gist is fine) and reply to @RockyTested with the link.
Rocky reruns or spot-checks every submission before it counts. Verified reruns will appear here with your handle.
🏅 Helper leaderboard
No verified reruns yet. Be the first!
Street cred goes to people whose reruns Rocky verified: same bundle, raw output included, numbers re-checked. How it works
Badge & stat card
Put the verdict badge in a README or post. It always links back to the measured results.
 With vs without

 Claim ledger
 Good uses
 Where it will fail you
 Where this repo comes from

 Real inputs beside real outputs
 Results, charted
 Score