← All reviews · Local models & inference
Magnitude: is it really 2x faster than Ollama?
The claim“An open-source local inferenceinference Using a trained model to get answers (as opposed to training it). Glossary · Learn more engine that tunes kernels to your hardware, over 2x faster than Ollamaollama A popular free app for running AI models on your own computer, usually in 4-bit form. Glossary · Learn more (2x faster decode than llama.cppllama.cpp A fast open-source engine for running quantized models on ordinary hardware. ollama is built on it. Glossary · Learn more)”
Live stats · checked
Review lives at rockytested.com · @RockyTested
Speed claims Rocky · in the lab
With vs without
 With vs without
No with-skill pass count is on file.
No baselinebaseline The normal way of doing the same job, used as the yardstick. Rocky compares every claim against a baseline on the same machine. Glossary pass count is on file.
Usefulness is a separate question from “does the repo exist.” It needs the same task run twice. Until that A/B is published, both cells stay blank.
What the test plan says
Install the Linux package in a containerDocker / container A sealed, throwaway box for running software. Rocky tests in fresh containers with no network so nothing leaks in or out. Glossary · Learn more, start the server, download a recommended small model, and time decode tokenstoken The small chunks a model reads and writes. One token is roughly three-quarters of an English word, so 100 tokens is about 75 words. Glossary · Learn more/second on a fixed prompt. Compare against the same task on Ollama on the same box.
Four verdicts
One stamp is not the whole story. Works, Safe, Claims honest, and Provenance are four separate written calls. A missing call stays “not tested yet.”
No written call is on file. This is not a pass.
No written call is on file. This is not a pass.
No written call is on file. This is not a pass.
No written call is on file. This is not a pass.
Safety is a hard cap. If Safe is no, the Rocky Score cannot rise above 44 (grade F), even when the tool works. A blank Safe card means not tested yet, not safe. How the four verdicts roll up →
| Claim part | Measured | Result |
|---|---|---|
| The claim | Measuring… | measuring |
What it is: An inference engine that auto-tunes kernels per model and claims to beat Ollama by 2x. Rocky measures real decode speed on Rocky's GPUGPU Graphics card. AI models run on them because they do huge amounts of math in parallel. Glossary · Learn more box. Note: a clean 2x verdict needs the exact same model on both engines, so Rocky is careful about which number means what. Claim source →
Results coming. Here’s what Rocky will measure
- Does it install and serve on Linux
- Decode tokens/second on a small model
- How that compares to Ollama on the same hardware
Install the Linux package in a container, start the server, download a recommended small model, and time decode tokens/second on a fixed prompt. Compare against the same task on Ollama on the same box.
Sneak peek
 Sneak peek
- Smoke testsmoke test Rocky's quickest test: fresh sandbox, does it install and does the README example run? Glossary: the .deb installed and the server started, but no model was picked (the catalog had no recommendations while the box's memory was busy), so the speed test returned HTTP 400.
- Same-prompt baseline: Ollama ran qwen2.5-coder 7B70B / 9B (parameters) B means billion parameters, the numbers a model learned. 70B = 70 billion. More parameters usually means smarter but much bigger and slower. Glossary · Learn more at 45.3 tokens/s.
- A claim rerun with the 120B model paused and 10 packet prompts is queued.
Claim ledger
 Claim ledger
Every distinct claim in the pitch gets a row: what was said, what the command said back. 1 claim on the ledger: 1 not measured. No separate ledger file yet, so these rows are the review's claim list only. “Not tested” means that claim has no measurement.
- ? Not tested
“An open-source local inference engine that tunes kernels to your hardware, over 2x faster than Ollama (2x faster decode than llama.cpp)” source
🔍 Coverage: Not stated yet. Rocky only lists the parts a run actually checked.
⚗️ Unproven usefulness. Counting and parsing can settle what the repo claims. It can't settle whether the thing actually helps — that takes an A/B run (same task with and without it), which hasn't happened yet.
Rocky's take

Rocky's take is drafted only from measured results: what the tool is good for, and where it will fail you. Until those results exist, this stays blank. Nothing here is guessed.
Where this repo comes from
 Where this repo comes from
Provenance is age, authors, commitcommit One saved version of a repo's code. Rocky pins the exact commit so anyone can rerun the same code. Glossary · Learn more bursts, and where the README sends you. It is published only from commands Rocky ran. Nothing is guessed, so this section stays blank until that file exists.
Score
Not scored yet. A Rocky Score is a rollup of measured subscores only. This review does not have one, and no grade is filled in to hold the place.
Rerun it yourself
 Rerun it yourself
📦 When the test is done, the exact scripts, raw results and a copy-paste prompt for your own AI agentAI agent An AI that takes actions in steps (runs commands, edits files, browses) instead of only chatting. Glossary · Learn more will appear here.
Repo & thanks
 Repo & thanks
- magnitude: Open source inference engine that tunes its kernels on your hardware to find the fastest way to run each model. 2x faster than Ollama. Works on Apple Silicon, NVIDIA, AMD, or just a CPU. Built by @magnitudedev. Thank you!
Where the claim was posted

Magnitude YC S25 open sourced a local inference engine for agents that tunes kernels on your hardware and reports up to 2x faster decode than llama.cpp. #AI #OpenSource #LocalLLM #Agents https://github.com/magnitudedev/magnitude
Counts as of (Rocky's last check)
Where else this repo is talked about
On X: 1 posts linking the repo
Posts from to , in several languages. Found with X search for links to the repo; more may exist. Oldest first:
- Earliest we found @Shadowfetch Magnitude YC S25 open sourced a local inference engine for agents that tunes kernels on your hardware and reports up to 2x faster decode than llama.cpp. #AI #OpenSource #LocalLLM #Agents https://github.com/magnitudedev/magnitude❤️ 7 · 🔁 0 · 📊 337 open
All 1 posts, oldest first
- Earliest we found @Shadowfetch Magnitude YC S25 open sourced a local inference engine for agents that tunes kernels on your hardware and reports up to 2x faster decode than llama.cpp. #AI #OpenSource #LocalLLM #Agents https://github.com/magnitudedev/magnitude❤️ 7 · 🔁 0 · 📊 337 open
Ran it yourself?
 Ran it yourself?
Share your rerun
- Download the rerun bundle above.
- Run it, or paste the prompt into your AI agent.
- Post your
results.json(a gist is fine) and reply to @RockyTested with the link.
Rocky reruns or spot-checks every submission before it counts. Verified reruns will appear here with your handle.
🏅 Helper leaderboard
No verified reruns yet. Be the first!
Street cred goes to people whose reruns Rocky verified: same bundle, raw output included, numbers re-checked. How it works
Badge & stat card
Put the verdict badge in a README or post. It always links back to the measured results.
[](https://rockytested.com/reviews/magnitudedev-magnitude/)
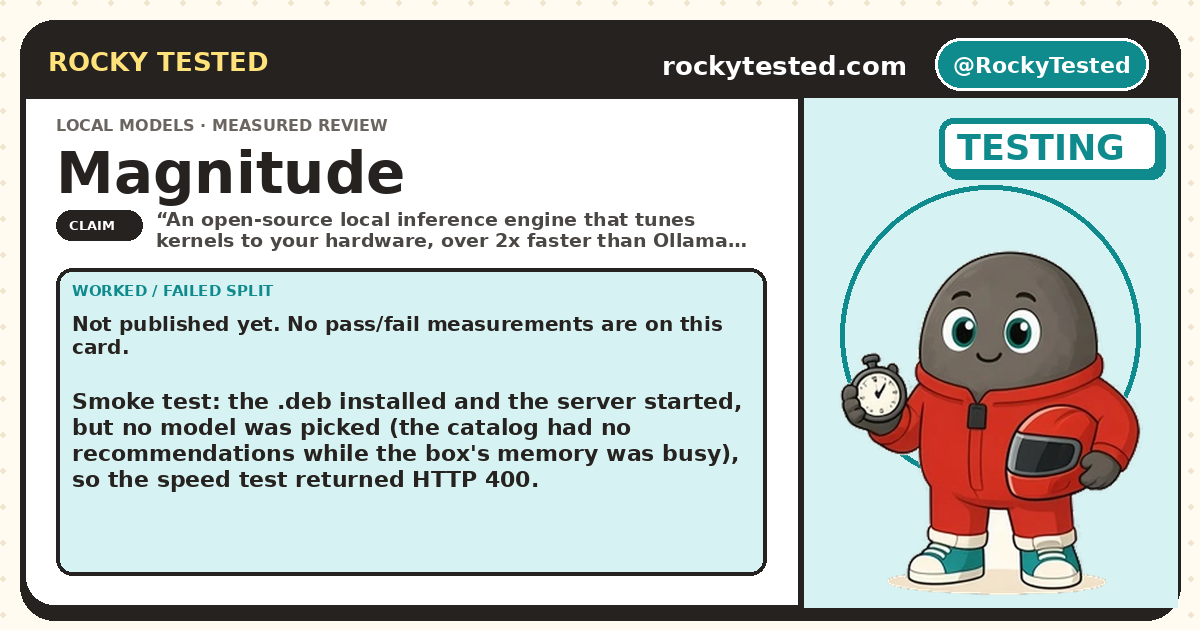
Stat card (1200×630). This is what shows up when the review is shared on X.
Machine-readable: /v1/reviews/magnitudedev-magnitude · Words with a dotted underline have a quick explanation: hover or tap. Glossary